Competitive gaming platforms use match results to update estimates of player skill, while some systems also incorporate individual performance data. These estimates help organize rankings and select opponents. Research from Microsoft Research explains that matchmaking depends on inferring ability from historical evidence, rather than treating one match as a complete assessment of a player.
For players comparing ways to improve elo, the important distinction is between raising an account’s rating and developing the ability that rating should represent. The linked commercial service offers ranking assistance. Understanding the underlying technology helps readers evaluate such claims without confusing account progression, statistical performance, and lasting competitive skill.
What Does Elo Actually Measure?
The Elo system estimates relative strength by comparing actual results with expected results. The International Chess Federation, known as FIDE, documents this approach in its rating regulations. Rating differences establish expected scores, and the gap between expectation and outcome determines the adjustment. A development coefficient controls how strongly those results change the rating.
Beating a stronger opponent therefore provides more positive evidence than beating a weaker opponent. Losing to a much stronger competitor is less surprising than losing to someone rated substantially lower. Consider an illustrative player expected to score 0.75: a win exceeds expectation by 0.25, while a loss falls short by 0.75. The calculation rewards unexpected success more heavily.
However, a rating remains relative to the competitors and rules within its system. FIDE describes its ratings as measurements against contemporary players. The practical implication is that numbers from different gaming platforms should not be treated as interchangeable. A score becomes meaningful through its player pool, calculation method, and competitive environment.
Visible Points Versus Hidden Matchmaking Estimates
Third-party platforms can make their ranking numbers prominent. FACEIT, for example, distinguishes its Elo score from its separate FACEIT Rating performance metric. Its current documentation states that ordinary match-by-match Elo changes depend on the result and the teams’ chances of winning before play begins. A strong performance metric does not automatically produce extra Elo.
By comparison, Riot Games separates hidden matchmaking rating, or MMR, from visible League of Legends ranks. MMR helps match players of similar ability. League Points translate progression into tiers and divisions. When hidden MMR sits above the displayed rank, victories can award more points and defeats can remove fewer, helping the visible position catch up.
This distinction explains why two players can receive different visible rewards without proving that one performed better during that particular match. Under Riot Games’ explanation, the relationship between rank and MMR matters. For players interpreting a dashboard, the useful question is whether a number represents matchmaking strength, recent performance, or progress through a reward structure.
Why Uncertainty Changes the Calculation
Elo is not the only approach. Statistician Mark Glickman developed Glicko to add rating deviation, a measure of uncertainty. A competitor with little recent evidence has a less certain estimate. His technical description explains that playing rated games reduces uncertainty, while time without competing increases it. The system therefore tracks confidence alongside the rating itself.
Microsoft Research’s TrueSkill also represents skill with an estimate and uncertainty. Unlike the original two-player setting associated with Elo, it explicitly handles teams, multiple competitors, and draws. Its published research describes inferring individual ability from team results. This addresses a central gaming problem: the scoreboard records a collective outcome, while matchmaking needs estimates for individual participants.
What Changes After a Seasonal Reset?
A seasonal adjustment should be interpreted separately from a match loss. FACEIT explains that its soft reset considers activity, win rate, and FACEIT Rating across a player’s last 50 games. Placement performance also helps establish the resulting position. Here, individual performance affects seasonal calibration even though the separate metric does not directly alter ordinary match-by-match Elo changes.
Performance adjustments also differ between algorithm families. The TrueSkill 2 paper from Microsoft Research incorporates additional evidence, including individual statistics, rather than relying exclusively on team standings. However, its authors emphasize aligned incentives. Rewarding a measurable action can encourage players to repeat it even when that behavior undermines the team’s actual objective.
Turning Match Evidence Into Better Play
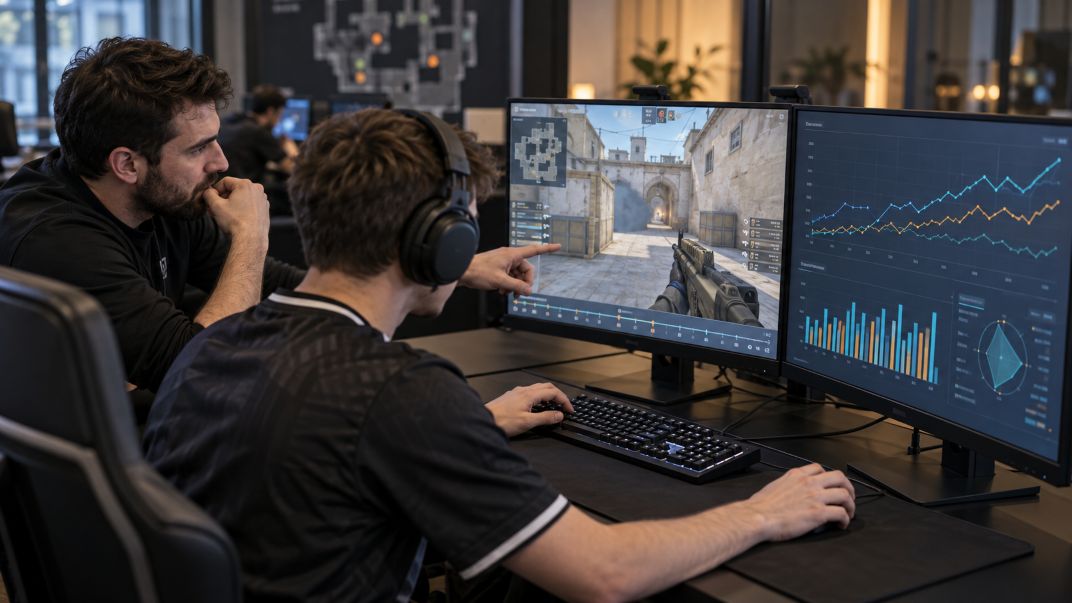
Analytics become useful when they lead to specific questions. FACEIT provides downloadable CS2 demos that players can replay. A practical review might examine repeated opening deaths, missed trading opportunities, or decisions made with limited information. These are suggested review priorities, rather than a guaranteed formula for advancement. Start with one recurring issue instead of chasing every statistic.
A coach can use those same replays to propose a practice plan. Players interested in connecting with gaming communities through live streaming can also use gameplay discussions to identify decisions worth reviewing. Turn that feedback into a concrete exercise: select one positioning habit, practice an alternative, and examine later matches for change. Treat rating movement as supporting evidence, while checking whether the targeted behavior actually improved.
Externally assisted ranking changes require a different interpretation. Riot Games explains that someone playing on another person’s account disrupts the connection between the account’s rating and its owner’s ability. This supports a basic evaluation principle: distinguish learning assistance from substituted performance. A higher account score alone cannot establish that its usual player developed stronger skills.
Where Rating Technology Could Go Next
Future improvements could combine uncertainty estimates, contextual performance signals, and clearer explanations of adjustments. Existing work from Microsoft Research provides foundations, but richer inputs still require validation against match outcomes. For players pursuing stronger competitive performance, the most useful systems would explain their limits and connect ranking progress with evidence of repeatable play.